Failures (platform admin)
What keeps going wrong, across every tenant, grouped by what actually failed—the page to read to decide what to fix, rather than the one for rescuing a single revision. It lives under Admin → Failures and requires the platform-admin role.
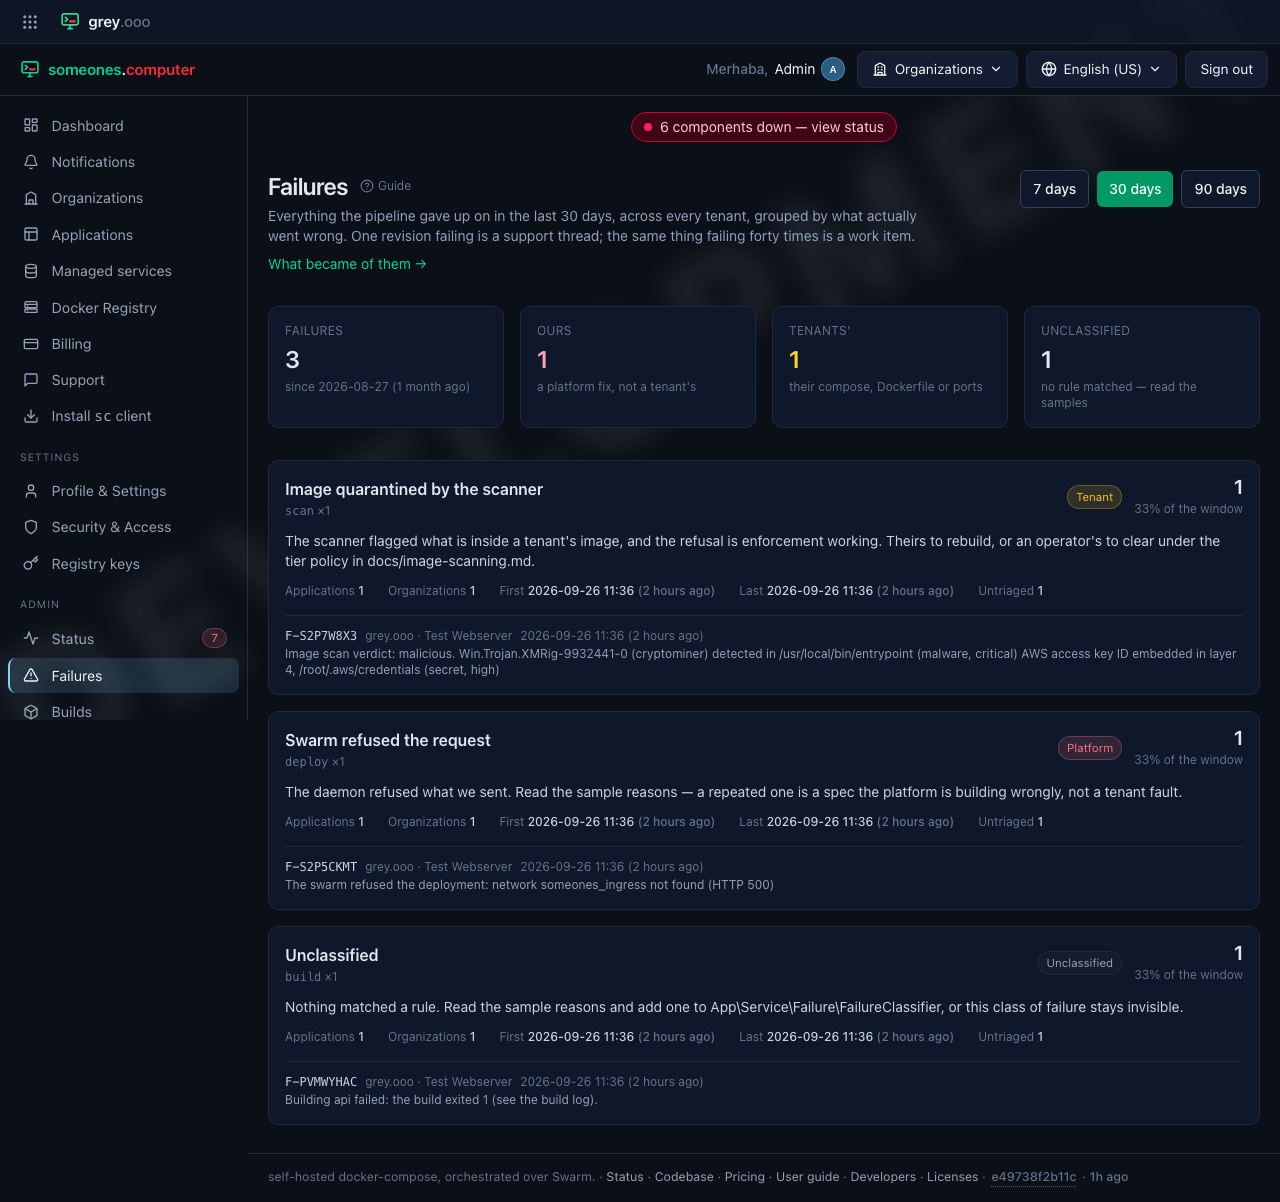
One revision failing is a support thread; the same thing failing forty times is a work item. That's the whole argument the page is built to make, read top to bottom:
- How many, and whose fault. Split three ways — Ours (a platform fix, not a tenant's), Tenants' (their compose, Dockerfile or ports), and Unclassified (no rule matched yet, worth reading the samples for). The zeroes stay on screen: "0 unclassified" is the statement that the rules are keeping up, not nothing worth showing.
- The kinds themselves, largest share first, each with the remedy for the class of failure rather than for one revision—what would actually stop this recurring.
- Three real samples under each kind, so a count can be checked against something rather than taken on faith. The reference is quoted as text, not linked—a failure's own page scopes to its owning organization's members, and an operator reading the rollup usually isn't one, so a link here would just 404 on them.
The window is 7, 30 or 90 days, and capped at the newest 2000 failures in it—the page says so out loud when a window hits that cap, because a capped count that stays quiet under-reports exactly the failure happening most.
Nothing failed in the window is the state this page hopes to render, and it says exactly that rather than standing an empty state in for it.
What became of them
The link under the intro opens Admin → Self-healing for the same window. That page explains how the platform heals itself and triages failures. It also follows each failure in the window forward, to one of these results:
| Result | The page counts |
|---|---|
| Recovery | A failure recovers when a later revision of the same application ran. The page also gives the median time to that revision |
| Triage | Failures triaged under an issue, failures triaged with no issue, and failures with no triage. The page also gives the median time to triage |
| Fix | One row for each tracked issue. It counts the failures of its kind before and after the first triage under the issue. "Quiet since" means none after |
The page doesn't read the tracker. The verdict comes from the failure table only.